
- Services
- Services
-
- Hire a Team
- Industry
- Company
- Company
-
- Case Study

Large language models have changed how businesses build AI-powered applications. From AI chatbots and virtual assistants to content generation and enterprise knowledge systems, LLMs can perform a wide range of language-based tasks.
However, a base Large Language Model (LLM) is not always enough for a production application.
Businesses often need an AI system that can work with private company information, access frequently updated data, follow a specific communication style, or perform a specialized task consistently.
This is where Retrieval-Augmented Generation (RAG) and fine-tuning come into the picture.
Although LLMs, RAG, and fine-tuning are often discussed together, they solve different problems.
In simple terms:
Understanding these differences is important when deciding how to build an AI application.
Large language models have changed how businesses build AI applications.
They now power chatbots, virtual assistants, content tools, and
enterprise knowledge systems.
However, a base Large Language Model (LLM) may not meet every
business need.
For example, a company may want an AI system that can:
This is where Retrieval-Augmented Generation (RAG) and
fine-tuning can help.
Although these approaches are often discussed together, they solve
different problems.
In simple terms:
Understanding these differences can help you choose the right approach
for your AI application.
nformation from external sources before generating a response.
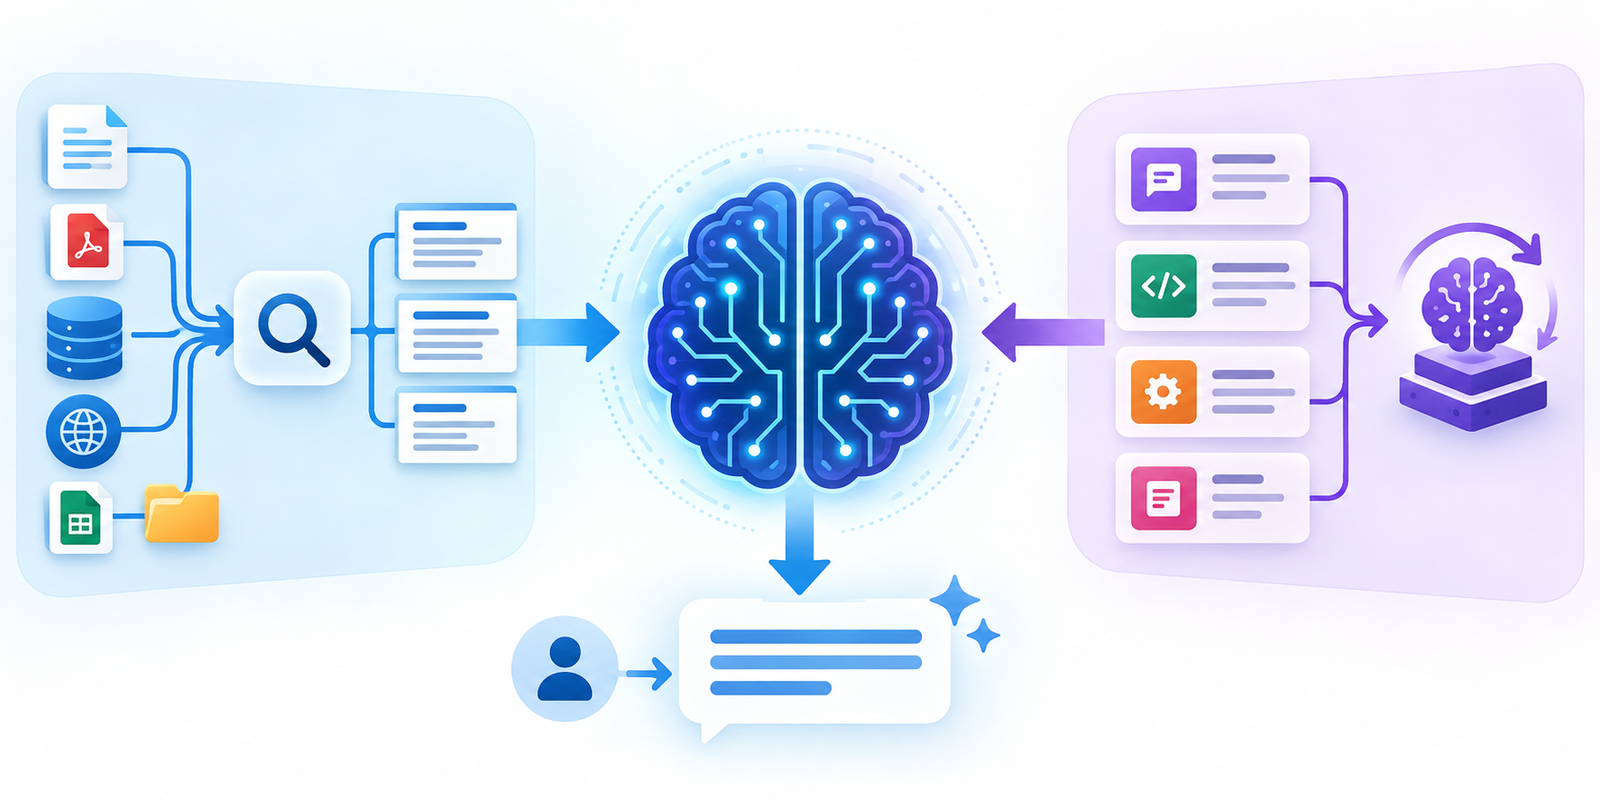
Instead of relying only on information learned during training, the system searches a connected knowledge source. It then provides the relevant information to the LLM as context.
A typical RAG workflow is:
User Question → Search/Retrieval → Relevant Documents → LLM → Answer
For example, imagine a company has thousands of internal documents.
An employee asks:
“What is our company’s work-from-home policy?”
Rather than expecting the LLM to already know the answer, a RAG system can:
RAG is especially useful when an application needs private, frequently updated, or domain-specific information.
A typical RAG architecture contains several components:
1. Data Ingestion
Documents, webpages, PDFs, databases, or other sources are collected.
2. Chunking
Large documents are divided into smaller sections so that relevant pieces can be retrieved efficiently.
3. Embeddings
The text is converted into numerical representations called embeddings.
4. Vector Database
The embeddings are stored in a vector database or another retrieval system.
5. Query Processing
When a user asks a question, the system converts the query into a representation suitable for retrieval.
6. Retrieval
The system finds the most relevant pieces of information.
7. Generation
The retrieved context is provided to the LLM, which generates the final response.
Fine-tuning involves further training a pretrained model with a dataset designed for a specific task or behavior.
Unlike RAG, fine-tuning does not simply provide new information during each request. Instead, it adapts the model through additional training.
For example, a company may want an AI system that can consistently:
Fine-tuning can help the model learn these patterns from examples.
However, fine-tuning requires suitable training data and evaluation. The quality of the examples can affect the resulting model behavior.
The easiest way to understand the difference is to look at what each approach changes.
| Approach | What it provides | Best suited for |
|---|---|---|
| LLM | General language and reasoning capabilities | General AI applications |
| RAG | External and current information | Knowledge-based applications |
| Fine-Tuning | Specialized behavior and output patterns | Task-specific applications |
Another useful way to think about them is:
LLM = Brain
RAG = External Knowledge
Fine-Tuning = Specialized Training
An LLM can answer questions using what it learned during training. RAG adds an external retrieval layer.
For example:
This makes RAG particularly useful for applications where information changes frequently.
Examples include:
Company knowledge bases
Product documentation
Customer support
Legal document search
Healthcare information systems
Internal employee assistants
Financial document analysis
E-commerce product information
RAG can also make responses more traceable when the application provides citations or references to the retrieved sources. OpenAI’s knowledge retrieval architecture, for example, focuses on generating answers grounded in connected data and citations.
RAG and fine-tuning are sometimes treated as competing approaches, but they solve different problems.
RAG is primarily about information.
It helps an LLM access information that exists outside the model.
Fine-tuning is primarily about behavior.
It helps a model learn how to perform a particular task or respond in a particular way.
Consider a customer support application.
You want the AI to:
You could potentially use:
RAG → Product documentation
Fine-tuning → Response behavior/style
These approaches can also be combined. Google Cloud notes that tuning and RAG can be used together when an application needs both specialized behavior and external knowledge.
A standard LLM may be sufficient when your application:
For example, a simple content-generation application may not require RAG or fine-tuning.
Starting with a standard LLM and good prompt engineering can also help establish a baseline before introducing additional complexity.
RAG is generally useful when your application needs access to external, private, or frequently changing information.
Consider RAG when:
For example:
A company could connect:
The AI can retrieve relevant content when answering employee questions.
RAG therefore allows the underlying model to remain general-purpose while providing application-specific context at runtime.
Fine-tuning becomes useful when you need the model to consistently perform a particular task or follow a particular response pattern.
Potential use cases include:
For example:
Customer message → Billing / Technical / Sales / Complaint
For example, converting unstructured text into a consistent JSON format.
Don’t create content simply to target keywords or AI systems. Write for your audience first and optimize the content naturally.
Fine-tuning can help a model better handle specialized terminology and task-specific patterns.
However, fine-tuning requires suitable training data and evaluation. Poor-quality or insufficient training examples can result in poor model behavior. Google Cloud identifies data requirements, overfitting, and other training considerations as important factors when evaluating fine-tuning.
Imagine an e-commerce company wants to build an AI customer support assistant.
The company has:
There are two different requirements.
The AI needs to know:
RAG can help here.
The application retrieves relevant information from the company’s data before generating the answer.
The company wants the AI to consistently respond in a particular format and style.
Fine-tuning may help here, depending on the task and available training data.
A production system could therefore look like:
User → RAG Retrieval → Relevant Context → Specialized LLM → Response
This combines external knowledge with specialized model behavior.
| Factor | RAG | Fine-Tuning |
|---|---|---|
| Main purpose | Add external knowledge | Adapt model behavior |
| Changes model weights? | No | Yes |
| Uses external data at runtime? | Yes | Not necessarily |
| Suitable for frequently changing data? | Yes | Less suitable as the sole mechanism |
| Requires training dataset? | No model fine-tuning required | Yes |
| Useful for response style? | Limited | Yes |
| Useful for proprietary knowledge? | Yes | Can be, but may not be the best mechanism for frequently changing knowledge |
| Easier to update knowledge? | Generally yes | Requires another training/update process |
| Can provide source citations? | Yes, when designed to do so | Not inherently |
Yes.
RAG and fine-tuning do not have to be mutually exclusive.
A system could use:
Fine-Tuning → Teach the model how to behave
RAG → Provide the information it needs
For example, a legal document assistant might use RAG to retrieve relevant documents while using model customization to enforce a particular output structure.
The important distinction is that RAG supplies context, while fine-tuning changes how the model behaves based on training examples.
RAG quality depends heavily on retrieval quality.
If the system retrieves irrelevant or incomplete information, the LLM may still generate a poor answer. Google Cloud specifically highlights retrieval quality and evaluation as important factors in reliable RAG systems.
| Your Requirement | Potential Approach |
|---|---|
| General AI assistant | LLM |
| Content generation | LLM |
| Summarization | LLM |
| Internal company chatbot | RAG |
| Product knowledge assistant | RAG |
| Frequently changing information | RAG |
| Document question answering | RAG |
| Specific output format | Fine-tuning may help |
| Consistent classification | Fine-tuning may help |
| Specialized response style | Fine-tuning may help |
| Private knowledge + specialized behavior | RAG + Fine-tuning |
RAG and fine-tuning solve different problems. RAG is primarily used to provide external information to an LLM, while fine-tuning is used to adapt model behavior through additional training. The appropriate approach depends on the application’s requirements.
No. RAG is an application architecture that works with an LLM. It adds a retrieval step that provides relevant external information to the model.
No. A RAG system can be built without fine-tuning the underlying LLM.
Yes. An application can use RAG for external knowledge and fine-tuning for specialized behavior.
RAG is generally easier when the primary requirement is updating the knowledge available to the AI. Updating the underlying learned behavior through fine-tuning requires another training process.
Fine-tuning can teach a model patterns, behaviors, terminology, and task-specific responses through training examples. However, for frequently changing factual information, a retrieval-based approach can be more practical because the application can retrieve current information at runtime.
LLMs, RAG, and fine-tuning are not simply three competing versions of the same technology.
They operate at different layers of an AI application.
LLM provides the general intelligence.
RAG provides access to relevant external knowledge.
Fine-tuning adapts the model to specific tasks and behaviors.
For many modern AI applications, the right architecture may involve more than one of these techniques.
The best starting point is usually to clearly define the problem, establish a baseline with a capable model and good prompting, and then determine whether the application needs external retrieval, model customization, or both.
As AI systems move from experimental chatbots to production business applications, understanding this distinction becomes increasingly important for building systems that are accurate, maintainable, and aligned with the application’s actual requirements.
Neha is a web technology enthusiast and content contributor at AssaptR, specializing in software development, custom web solutions, eCommerce, and digital marketing. Her articles focus on the latest industry trends, best practices, and actionable strategies that help businesses build secure, scalable, and high-performing digital products.
9. When Should You Use an LLM?
11. When Should You Use Fine-Tuning?
11.4. Domain-Specific Terminology
12. RAG vs Fine-Tuning: A Practical Example
13 . Key Differences Between RAG and Fine-Tuning
14 . Can You Use RAG and Fine-Tuning Together?
15 . Advantages and Limitations
15.3.1. Advantages of Fine-Tuning
15.3.2. Limitations of Fine-Tuning
16 .LLM vs RAG vs Fine-Tuning: Simple Decision Table
WhatsApp us